what is this
Every session with an AI coding agent starts from zero. The decision you made yesterday, the bug you fixed last week, the reason the auth code is shaped the way it is - gone. You explain it again, or the agent guesses.
Gingugu is a memory server the agent talks to over the Model Context Protocol. It stores memories as typed records - fact, decision, bug, pattern, architecture, workflow, preference, context, capability - links them into a graph, scores them by relevance, freshness and trust, and hands the right ones back at the start of a session or the moment a prompt or tool call touches them.
Storage is the easy half. A memory server an agent never writes to is an
empty database, so the protocol ships too: gingugu init wires
a repo so the agent loads memory first, saves as it goes, and gets
reminded by hooks the harness runs whether or not it feels like it.
how it is built
The design calls that set it apart. Each one is a property of the code, not a promise.
a graph, not a pile
Memories link by typed edges that record what search cannot infer: supersedes, contradicts, caused_by, parent_of, child_of. Recall finds the best matches with hybrid search (BM25 over SQLite FTS5 plus local embeddings, fused with reciprocal rank fusion), then spreading activation wakes their neighbours - including ones that have gone dormant. Tap a memory.
recall(...)
a session, replayed
What the agent sees in a wired repo - nothing here is asked for by hand.
codebase x-ray
code_xray maps a repo's import graph - Python,
TypeScript/JavaScript and Go, parsed and never run - and ranks files by
directed PageRank. The map arrives before the work does: the first
read into a repo brings the files everything leans on, and each file
the agent opens comes with who imports it and how far a change would
reach. Before an edit it answers: what does this change reach, and which
tests should run? It stops an edit only when the edit is blind - a file
other files import that the agent never read - and right after every
other edit it names who calls what changed and the tests nearest them. Remove
a key an emitted line carried - "status", a keyword argument,
an object key - and it lists the files that still read it, tests, docs
and monitor queries included, as text matches rather than import edges.
When a shell command writes behind its back, a sed or a
codegen script, the answer comes the moment the command returns. Hand
an agent a branch and the brief gives it the same map for the whole
change - changed files by rank and everything they reach - even an
agent no hook ever fires for. In Python, TypeScript, JavaScript and Go it
sees functions, not just files, and callers lists everything that reaches one
function by call - a lower bound, because a call it cannot prove is
counted, never guessed. And it keeps score: the tests it named are
checked against the tests that then fail. It remembers what a file has
cost, too: the first read of a file, and the stop before a blind edit,
bring the bugs and decisions in that repo's memory that name it - a bug
about one file outranks a plan that names thirty. It reads git history
as a second graph: the hotspots where work piles onto load-bearing code,
and the files that always change together though neither imports the
other - the dependency no import line shows, named on the first read of
either file. And it maps the blind spots: files the rest of the code
leans on that no test imports or is named for, ranked by reach over how
few people have touched them - where a change goes furthest with the
least review. And it maps the attack surface: every route, MCP tool, CLI
command and script entry point, with the dangerous calls each one
reaches - a shell, an eval, a deserialiser, a query
assembled at runtime, a file write, a secret, the network, a database
table - most dangerous and nearest first, with the shortest path to
each. A route is named by its real URL, prefixes from the files that
mount it included, once for every place it is mounted - read from
FastAPI, Flask and its REST extensions, Django and its REST framework,
Express, Koa, NestJS, Next.js route files, and Go's standard library,
gin, echo and chi. And it joins
the two ends of a request: each route comes with the files in the repo
that call it - a frontend's fetch, a script, a test - and
each call with the route that answers it, or with none, so a typo or
an endpoint renamed on the other side is named the moment the edit
lands, and so is a route still called after it is gone. And the surface
arrives as the work does: the first read of a file names its entry
points and the sinks they reach, and an edit that makes a dangerous
call newly reachable from outside says so the moment it lands. Your
checkout is read on your machine, even when the brain lives elsewhere.
edit ...
the agent board
Agents sharing a brain leave each other posts: addressed, read once
(a task stays up until someone claims it), never ranked - so they never pollute memory. Claude Code gets a post with
your next prompt, gingugu board watch wakes an idle Codex agent
when one lands, and a reply goes back to the session that asked. A handoff that names its branch - xray: main..fix/rotation
- arrives with the x-ray of that change, drawn from the reader's own
checkout, and a post sent from a branch is reminded once to name it.
see your brain
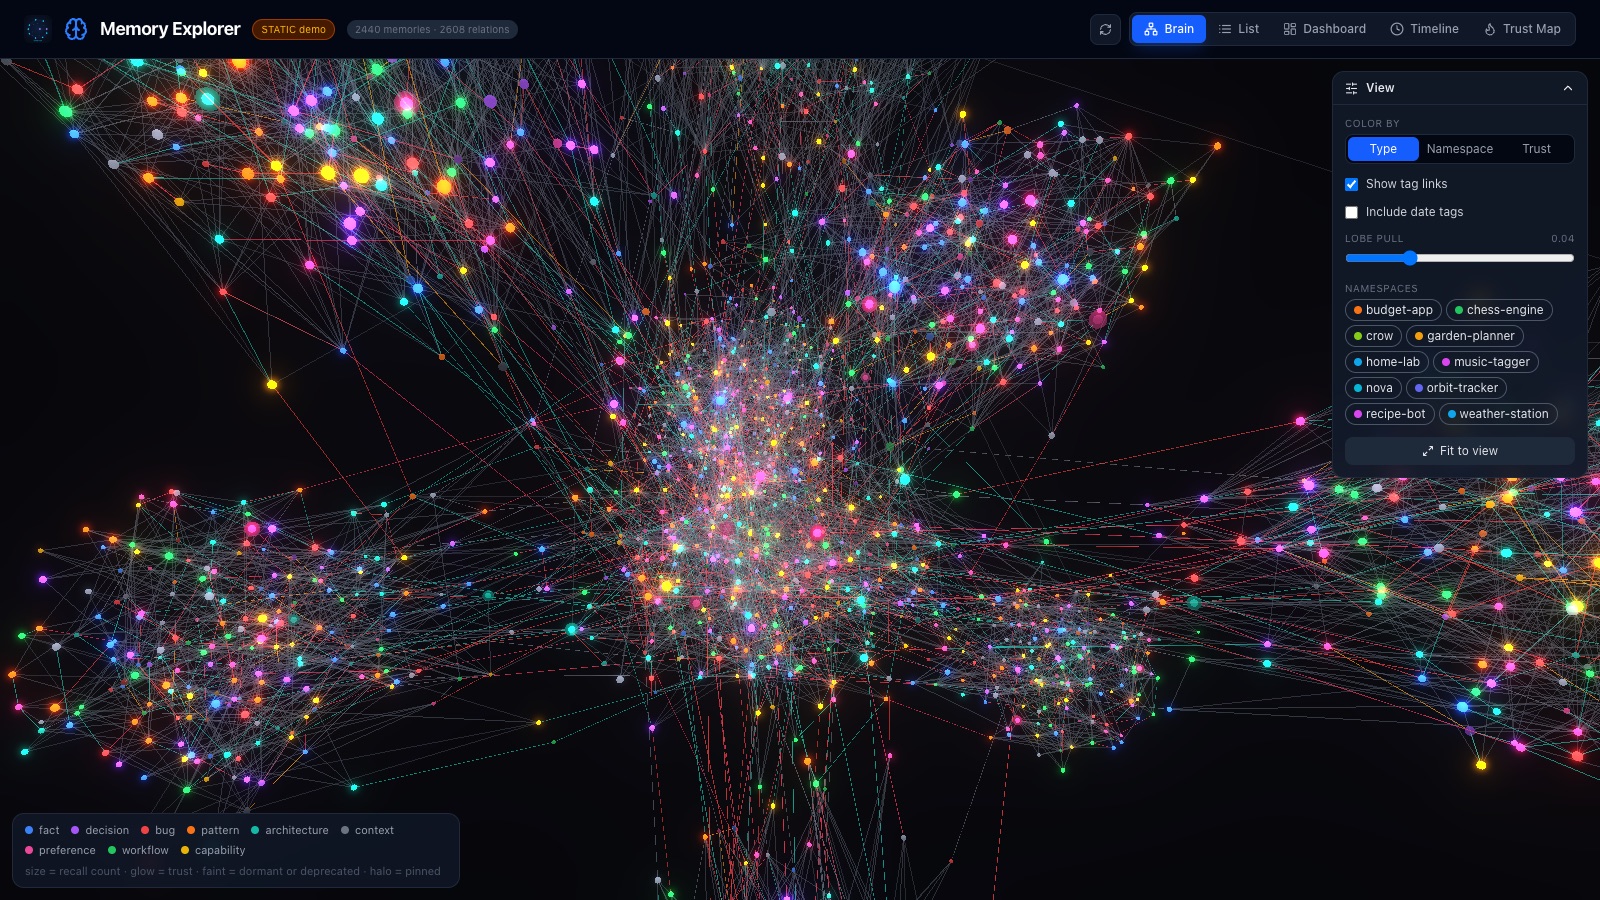
gingugu ui opens the Memory Explorer: a 3D brain with one lobe
per namespace, a list, a dashboard, a timeline and a trust map. It is a
read-only observer - it cannot change a memory.
 [ open the live demo ]
the toolbox
23 MCP tools. Hover or tap one.
> select a tool
install
uv tool install gingugu
or pip install gingugu. Then in a repo run gingugu init.
It wires Claude Code by default; --client windsurf|cursor|cline
for the others. Any MCP client can point at it directly.
Retrieval numbers come from 30 labelled questions against a working brain: a regression baseline, not a public benchmark. The runner ships in the repo - point it at your own store.